memory_index — AgentTeamsModule
Build and query a search index over durable agent team documentation.
Used by @navigator, @adversarial, and @work-summarizer to retrieve relevant work summaries, CHANGELOG entries, and plan artifacts from previous sessions. Supports two retrieval strategies: BM25 lexical (default, high precision for keyword queries) and sparse tf·idf vector cosine similarity (optional, better for thematic/semantic queries). Both are stdlib-only, deterministic, and have no external dependencies.
Source:
agentteams/memory_index.py
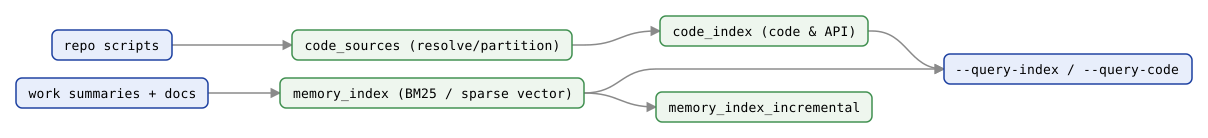
Retrieval families at a glance
memory_index (prose → BM25 / sparse vector) is one of two retrieval families; the other is
code_index (repo scripts → code_sources partitions), with
memory_index_incremental as an in-place-patching satellite.
Generated deterministically from scripts/gen_api_cluster_figures.py.
Design Principles
- Two strategies, no dense embeddings — a deliberate design boundary, not a "later tier." BM25 lexical (default) and sparse cosine vector; both stdlib-only, no external ML dependencies. ("No embeddings" here means no dense learned embeddings; the sparse tf·idf strategy does build sparse term-frequency vectors, which are not dense neural embeddings.) The reserved fields
vector_model_idandvector_dimexist for forward-compatibility metadata only; dense embeddings are intentionally out of scope for this module. Consumers needing dense vectors should layer their own retrieval atop the indexed sources rather than expecting the module to grow an embeddings backend. - Durable sources only — Caller passes explicit source paths; module never globs ignored directories
- Robust to absence — Empty source list → empty but valid index (no error)
- Graceful degradation — Per-paragraph passage scoring (I2, I9) with backward-compatible snippet fallback
- Explicit contract metadata — Build/runtime ownership, fallback policy, and vector runtime mode are encoded in the index payload
- Deterministic — A full rebuild (
build_memory_index) over the same source set always yields the same scores; suitable for testing and reproducible workflows. The feature-flagged incremental update path recomputesvector_norm_sqfor the changed document, so it produces the same per-document values a full rebuild would (only thebuilt_at/index_build_idmetadata differs).
Constants
MEMORY_INDEX_SCHEMA_VERSION
Source:
agentteams/memory_index.py
Current schema version for memory index artifacts. Used to detect compatibility between build and consumer versions.
Type: str
Current value: "1.3"
Schema versions:
| Version | Change |
|---|---|
| 1.1 | Legacy: no per-paragraph storage; single snippet field only |
| 1.2 | Per-paragraph passage storage; paragraphs list added; query_index() returns snippets list alongside legacy snippet alias |
| 1.3 | Adds explicit contract metadata (index_format_version, index_build_id, index_write_owner, vector_runtime_mode, fallback_policy, source_fingerprint) and per-document source_hash |
Functions
build_memory_index(sources, *, project_name="", framework="", root=None)
Source:
agentteams/memory_index.py
Build a BM25 search index over durable text sources.
Args:
sources(Iterable[Path | str]) — List of file paths to index (work summaries, CHANGELOG, plan artifacts, etc.). Missing or unreadable files are silently skipped.project_name(str, keyword-only) — Optional project name to embed in the index metadata. Default:"".framework(str, keyword-only) — Optional framework name to embed in the index metadata. Default:"".root(Path | None, keyword-only) — Project root. When given, each document'spathis stored relative to it; the index is a committed artifact, so absolute paths leak the operator's home directory and username (2135 in this repository's own index before the change). Relativization happens here rather than at serialization sosource_fingerprint, derived from the document paths, describes the paths actually stored. A source outsiderootstays absolute — it is genuinely external. Default:None, preserving absolute paths for existing callers.
Returns: dict[str, Any] — Index dict with keys:
- artifact_type: "memory-index"
- memory_index_schema_version: Current schema version
- index_format_version: Serving-format identifier for the artifact structure
- index_build_id: Build fingerprint for this specific index emission
- index_write_owner: Writer ownership marker (agentteams.build_team)
- vector_runtime_mode: Runtime strategy implementation (sparse-tfidf-cosine)
- vector_model_id, vector_dim: Reserved nullable fields for forward-compatibility metadata. Always null for this module — dense embeddings are intentionally out of scope (see Design Principles). Consumers that layer their own dense retrieval may use these fields in their own derived artifacts.
- fallback_policy: Declares non-blocking fallback semantics
- source_fingerprint: Stable digest across indexed document path/hash pairs
- project_name, framework: Supplied metadata
- built_at: ISO-8601 timestamp
- source_count: Number of files supplied
- documents: List of indexed documents (with title, path, snippet, paragraphs, length, source_hash, etc.)
- postings: Term-to-document frequency postings (BM25 substrate)
- avgdl: Average document length (for BM25 normalization)
- N: Total document count
Behavior:
- Empty source list yields a valid empty index (no error).
- Files are read once; I/O errors are silently skipped (robust to in-flight churn).
- Paragraphs are extracted per-document (up to 20 substantive paragraphs per source); each truncated to 480 characters for compact JSON.
- Headings and non-substantive paragraphs are filtered out.
- Stopword list (small, generic English set) is applied during tokenization.
Raises:
- No exceptions; I/O failures are silently skipped.
is_index_stale(index, sources, *, root=None)
Source:
agentteams/memory_index.py
Check if any source file is newer than the index's built_at timestamp or no longer matches recorded content hashes.
Args:
index(dict[str, Any]) — Index dict frombuild_memory_index().sources(Iterable[Path | str]) — Original source paths (same list used for build, or a subset).root(Path | None, keyword-only) — The project root the index was built against. Required when the index stores relative paths: without it eachpathresolves against the process CWD, the hash read fails, and the index reports stale on every call — triggering a full rebuild per query. Default:None, for indexes storing absolute paths.
Returns: bool — True if any source content hash mismatches indexed source_hash, or if any source mtime > index built_at (index is stale); False otherwise.
Safety: Invalid/missing timestamps are treated as stale (conservative). Missing/unreadable files for hashed documents are also treated as stale.
query_index(index, query, *, k=5, strategy="lexical")
Source:
agentteams/memory_index.py
Return the top-k documents for query using the specified retrieval strategy.
Args:
index(dict[str, Any]) — Index dict frombuild_memory_index().query(str) — Free-text search query (e.g.,"behavioral drift drift detection").k(int, keyword-only) — Number of top results to return. Default:5.strategy(str, keyword-only) — Query strategy. Default:"lexical"."lexical": BM25 term-frequency ranking. High precision for keyword/exact-term queries."vector": Sparse tf·idf cosine similarity. Better for thematic/semantic queries where multiple concepts must be related. Stdlib-only, deterministic, <100ms at N=180 docs.- Raises
ValueErrorfor any other value.
Returns: list[dict[str, Any]] — Ranked results (highest score first). Each result dict contains:
- doc_id: Internal document ID
- path: Source file path
- title: Extracted heading (first # line) or filename
- score: Relevance score (rounded to 6 decimal places; BM25 for lexical, cosine similarity for vector)
- confidence: "reliable" / "candidate" / "weak", computed from score against per-strategy thresholds (lexical: ≥3.0 reliable, 1.0–3.0 candidate; vector: ≥0.30 reliable, 0.20–0.30 candidate). Replaces threshold prose several templates used to restate by hand — see agentteams/templates/universal/conflict-resolution.template.md's memory_index_consultation fence for the canonical wording consumers cite.
- snippet: Best single passage (backward-compat; always present)
- snippets: List of up to 3 best-matching passages (new in v1.2; dynamic passage scoring; present even for v1.1 indexes)
Behavior:
- Query terms are tokenized and stopwords removed.
- If no query terms match the index, returns empty list.
- Ties are broken deterministically by
(-score, doc_id)so callers see stable ordering. - Passage scoring is intra-document only (relative ranking within each document); best paragraphs are ranked independently.
- Backward-compat: v1.1 indexes (no
paragraphsfield) return the stored staticsnippetfor all results. - Both strategies are stdlib-only with no external dependencies.
- Duplicate documents are returned as separate hits, deliberately. Byte-identical files at different paths can score identically and occupy consecutive slots; collapsing them was considered and rejected because a collapsed hit must report one path, and which path is right depends on the caller. Callers that need de-duplication should do it on content hash at their own layer, or raise
k.
redact_local_paths(text)
Source:
agentteams/memory_index.py
Replace absolute home-directory paths (/Users/..., /home/..., C:\Users\...) in text with a <path> marker before it is stored. Snippet text is committed inside the index artifact, so any such path surviving in a source document would otherwise be republished into version control — measured 2026-07-30, 49 occurrences naming an unrelated repository. Called on every paragraph/snippet build_memory_index extracts (and by the legacy single-snippet fallback), so this is the one choke point every stored passage passes through. Only the leading home-prefixed path component is matched; a repository-relative tail elsewhere in the sentence survives.
Args:
text(str) — A snippet or paragraph about to be stored in the index.
Returns: str — text with every absolute home path replaced by <path>.
Query Strategies
The memory index supports two retrieval strategies, each optimized for different use cases.
Lexical (BM25) — Default
Algorithm: Probabilistic information retrieval using term frequency and inverse document frequency.
Use when: - You have specific keywords ("where is the delivery-procedure doc?") - You want exact-term matches ("when did we add feature X?") - Speed is the top priority (slightly faster than vector)
Example:
Vector (Cosine Similarity) — Optional
Algorithm: Sparse tf·idf vector-space scoring with cosine similarity — stdlib only, no dense embeddings (see Design Principles).
Use when: - Searching for thematic overlaps ("what's our policy on error handling?") - You want documents related to ALL query terms, not just some - Generating summaries and need to avoid duplicating prior themes
Example:
Strategy Selection
Is your query a simple keyword lookup?
  ├─ YES → Use lexical (faster, exact matches)
  └─ NO → Is it a thematic query with multiple concepts?
        ├─ YES → Use vector (semantic matching)
        └─ NO → Use lexical (safe default)

Did your first query return low-confidence results (empty or score < 0.1)?
  ├─ YES → Retry with the other strategy
  └─ NO → Use the result
Performance
Both strategies are fast and have no external dependencies:
| Operation | Corpus Size | Time (ms) |
|---|---|---|
| Build index | 180 docs | <100 |
| Query (lexical) | 180 docs | 20–50 |
| Query (vector) | 180 docs | 40–80 |
| 25 queries | 180 docs | <2500 total |
See tests/test_memory_index_performance.py for detailed benchmarks.
BM25 Tuning
Grid search over the AgentTeams N≈10⁵-token corpus (2026-05-19) with 10-document eval set:
| Parameter | Candidates | Selected | Rationale |
|---|---|---|---|
| K₁ | 1.2, 1.5, 2.0 | 1.5 | Textbook default; no differentiation in eval |
| B | 0.75, 0.85, 1.0 | 0.75 | Textbook default; no differentiation in eval |
All 9 combinations achieved 10/10 top-1 accuracy on the eval set. Parameters are non-differentiating at this corpus scale; textbook defaults are retained for reproducibility.
Typical Usage
from pathlib import Path
from agentteams.memory_index import build_memory_index, query_index

# Build index from durable sources
sources = sorted(Path("workSummaries").rglob("*.md")) + [
  Path("CHANGELOG.md"),
  Path("README.md"),
]
index = build_memory_index(sources, project_name="agentteams", framework="copilot-vscode")

# Query for relevant documents
results = query_index(index, "behavioral drift detection", k=3)

for r in results:
    print(f"📄 {r['title']} ({r['score']:.3f})")
    print(f"   Path: {r['path']}")
    print(f"   → {r['snippet'][:100]}...")
    for i, passage in enumerate(r['snippets'], 1):
        print(f"   [{i}] {passage[:80]}...")
Strategy And Staleness Decision Flows
Query Strategy Decision
from agentteams.memory_index import query_index

hits = query_index(index, "delivery receipt fingerprint parity", k=5, strategy="lexical")
if not hits:
  # Retry thematic match when lexical confidence is low
  hits = query_index(index, "delivery verification workflow", k=5, strategy="vector")
Practical guidance:
- Start with
lexicalfor exact-term lookups. - Retry with
vectorfor thematic queries or sparse lexical matches.
Staleness Handling Decision
from agentteams.memory_index import is_index_stale

if is_index_stale(index, sources):
  # Caller policy: rebuild before serving query results
  index = build_memory_index(sources)

hits = query_index(index, "workflow 11 final check", k=5)
CLI Flow (Operator Path)
agentteams --description brief.json --refresh-index
agentteams --description brief.json --query-index "security gate overwrite clearance" --query-k 5 --query-strategy lexical
agentteams --description brief.json --query-index "policy guidance for update safety" --query-k 5 --query-strategy vector
Use --refresh-index after editing durable sources (for example workSummaries/, CHANGELOG.md, README.md, docs_src/*.md, references/*.md) before query-heavy sessions. See the CLI reference for the full index-flag surface.
Query CLI synchronization behavior:
--query-indexnow checks staleness before serving results.- When stale, it auto-refreshes
references/memory-index.jsonand then executes the query. --refresh-indexremains useful for proactive pre-warm workflows and CI/operator scripts.
Incremental update mode (feature-flagged) — see memory_index_incremental:
- Set
AGENTTEAMS_MEMORY_INDEX_INCREMENTAL_SED=1to enable a reliability-first incremental updater. - The updater generates and applies
references/memory-index.incremental-update.sedfor eligible updates. - Eligibility is intentionally narrow (single changed document, no source set changes, stable term vocabulary).
- On any ineligible shape or sed/validation failure, behavior falls back to canonical full rebuild.
Domain boundary note:
- The
strategy="vector"option inmemory_indexis local sparse tf·idf vector-space ranking for memory-history retrieval only. - It is separate from relational retrieval-integrator validation contracts in other module domains.
Integration Notes
- Durable sources (I7): Caller is responsible for passing explicit source paths; the module never globs
tmp/or ignored directories - Absence safety (I5): Empty source list is valid; returns a skeleton index with zero documents
- Stale detection (via
is_index_stale(), see the stale-detection guide) — Query CLI auto-refreshes stale indexes; callers may still refresh proactively - Fallback protocol —
@navigatorconsults this index first, then opens referenced files for detail, then falls back to filesystem search - Consumer-declared source dirs:
brief.jsonmay add amemory_index_extra_dirslist — project-relative directories (recursive*.mdscan) or glob patterns (literal expansion). Absolute paths are rejected; traversal is rejected viaPath.resolve+relative_to; symlink escapes are rejected via a post-globos.path.realpathcheck. Resolved paths are threaded throughanalyze.build_manifestandbuild_team._memory_index_sourcesand merged with the default source set.
Consultation Clause (memory_index_consultation v=2)
Audit / validation / research agents (@conflict-auditor, @conflict-resolution, @quality-auditor, @technical-validator, @retrieval-integrator, @tool-doc-researcher) carry a fenced memory_index_consultation clause that runs agentteams --query-index directly inside their workflow loop rather than round-tripping through @navigator.
v=2 thresholds (per-strategy):
- Lexical (default): reliable hit at score
≥ 3.0. Single-term queries always go lexical-first. - Vector fallback: triggered on zero hits OR zero query-term overlap (single-term false-positive guard). Reliable at score
≥ 0.30. This floor is corpus-specific guidance, not a mathematical cap — cosine ∈ [0,1] and high values (≥ 0.5, up to1.0) are legitimate when query terms concentrate in a focused or short document, so do not treat≥ 0.5as anomalous. - Either strategy:
< reliablebut> 0→ "candidate" — open the snippet's source file, never block on the index.
Empirically: corpus expanded 69 → 198 docs on example-collector, lexical reliable rate 3/4 → 4/4, vector reliable 0/9 → 3/9 + 1 candidate.
Schema Compatibility
The index is forward-compatible within major versions:
- v1.1 → v1.2 upgrade: Index built with v1.1 can be queried with v1.2 reader (fallback to static snippet if
paragraphsmissing). - v1.2 → v1.3 upgrade (current): Adds explicit contract metadata (
index_format_version,index_build_id,index_write_owner,vector_runtime_mode,fallback_policy,source_fingerprint) and per-documentsource_hash. Additive: a v1.2 index still queries correctly (readers ignore fields they don't recognize), thoughis_index_stale()falls back to mtime-only staleness detection until the index is rebuilt and gainssource_hashper document. - v1.3 → v2.0 (hypothetical): Schema version bump indicates breaking change; consumer must opt-in.
Always check memory_index_schema_version before consuming an index artifact.
See also
memory_index_store— how the index is laid out on disk: compact lines, and size-capped shards above 20 MiB that--query-indexreads directly.code_index— the parallel retrieval index over repository scripts and the external APIs they call.